Loading video…
Sound

original sound - hatsunama
Hatsu | Ai · Original audio
0:00–:––
Playing this video’s own audio, so you’ll hear the creator over the sound.
The video addresses a common pain point for AI enthusiasts: running large models on consumer hardware. By explaining a technique (memory-mapped inference) that bypasses RAM limitations and providing clear, actionable steps for different operating systems, it offers significant value to the target audience.
This video explains how to run AI models on your computer using llama.cpp, even if your hardware is not rated for it. It details the necessary components like a fast SSD and a quantized GGUF model, and provides instructions for both Windows and Mac users on how to set it up and run the AI model efficiently by memory mapping it to the SSD.
How to run 2x the ai model size your computer is rated for #ai #news #howto #local #fyopppppppppppppppppppp
The Ai "How To" Everyone asked for
Introduction to running AI models locally
Explaining memory-mapped inference
Listing hardware requirements (PC, SSD, RAM)
Demonstrating setup for Windows and Mac
Explaining the challenge with FPGAs
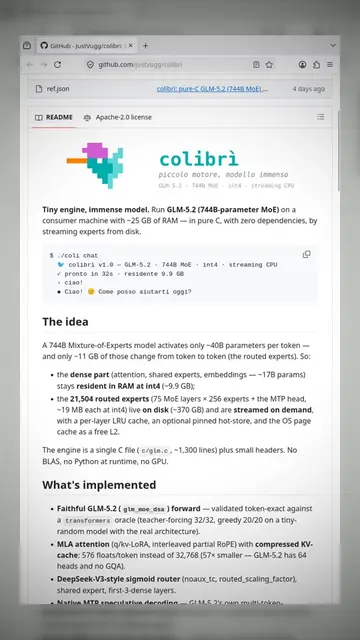
The video demonstrates how to use llama.cpp, an open-source tool for running AI models locally. It shows command-line interface commands and mentions the need for a quantized GGUF model.
So hit that save button. Let's get in.
Playing this video’s own audio, so you’ll hear the creator over the sound.
Open-source software for running large language models locally, for developers and AI users
All time.
Promotes 7 products. Create free account to see more.
Outliers and viral hits: their videos on Overshot, all time.