Loading video…
All breakouts Open on TikTok
No preview available · watch on TikTok below
6.2AI Tools
Post
Post by @lord.luke5
@lord.luke5
3.3K followers · usually 2.7K views a post
Views
28.6K
Likes
1.0K
Comments
41
Shares
56
View velocity
+3.0K views over 8.9d · ~333/day · 9 observations
We’re still analyzing this post.
Original caption
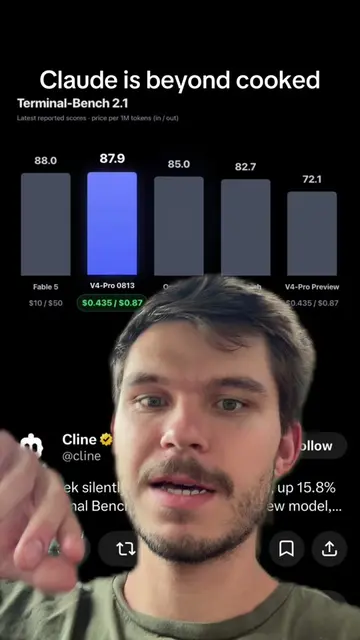
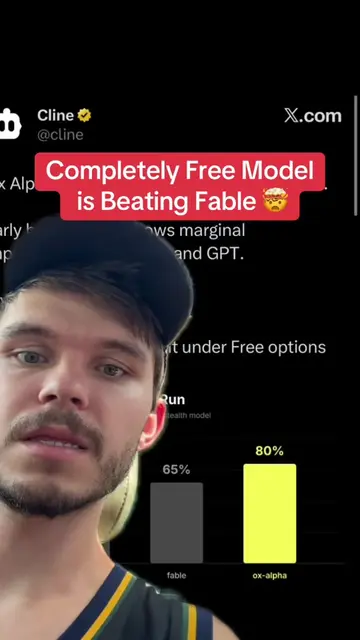
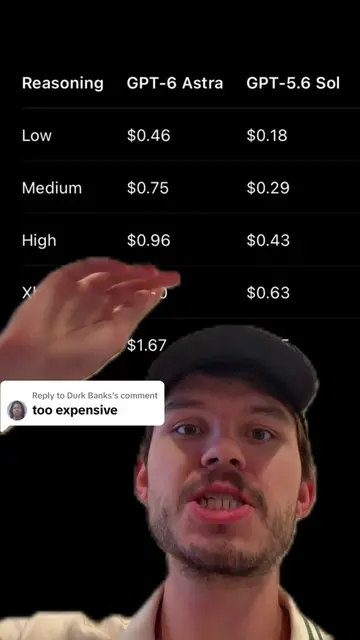
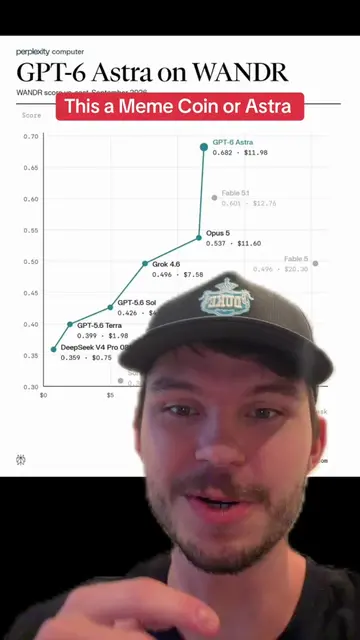
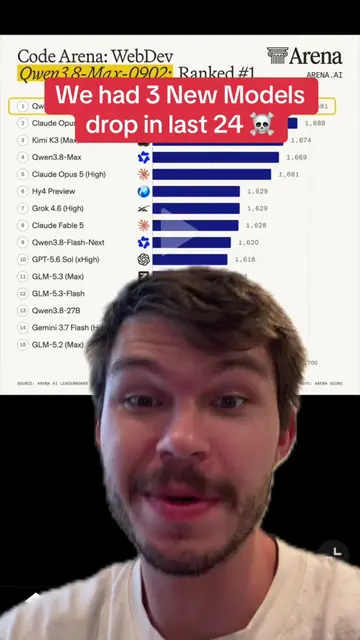
Replying to @Andrea-Leon ASTRA MIGHT BE ON A DIFFERENT LEVEL 😭 I thought Fable 5.1 was going to be the model to watch… but Astra is looking terrifying. On this internal ExploitBench test, Astra’s success rate scales to nearly 40%, while GPT-5.6 Sol — already an insanely capable model — sits much lower even with significantly more output tokens. And then you look at how expensive frontier intelligence is becoming to benchmark/run… these next-generation models are getting serious. Obviously, this is one benchmark and not the whole story, but if Astra performs anything like this in real-world agentic tasks, we could be looking at a massive jump. What do you think about Astra? Is this actually the next big leap in AI? 👀 [ASTRA, GPT-5.6 Sol, Fable 5.1, AI models, AI benchmarks, agentic AI, OpenAI]
More from @lord.luke5
More breakout videos from this creator.