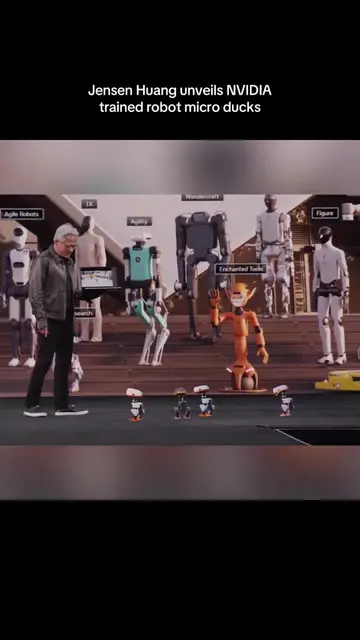
Hello my friends, Russell here from Superintelligent AI and I've had some great conversations with you when we've been talking about the world simulation engine from NVIDIA, also known as GROOT and the Omniverse. And today, rather than just talk about it, I'm going to show you a few things. I'm going to go ahead and spin the camera around and talk through a couple of things. Main thing to understand is that the goal and the objective and the language learning models that everybody's all hyping up are really food or fodder or fertilizer for the world engine. So on NVIDIA's own website, although this video is private, video is private on Google, you can see thousands of, hundreds if not thousands of robots all training in this simulated environment in a virtual space. And the idea is to create a better compute stack so that they can continue to train and they can basically experience every simulation possible using the GROOT system. Okay, we're talking Metamorph and all these other things. And what this means is that there's no type of scenario or action in the physical world that they can't do zero shot on. Zero shot means that they are not necessarily experienced in the physical world at all. It's just a virtual. And this is the kind of dexterity and things that you can see that the robots can do. Okay, they can do incredibly difficult things that are very difficult for humans even do. Okay, and this is just scratching the surface of what's possible. So we're dealing with basically monster amounts of infrastructure. I don't know how much you can see, but this video I'll put up for everybody to look at. These things are doing anything including playing drums, but one of the bigger things I want to bring your attention to is even though these things can replace humans in all kinds of ways, here's the thing that's very interesting, mirror neurons. In human psychology, there's imitation mechanisms we have called mirror neurons. Now there's a whole bunch of factors, but these things are imitating humans in real time, so they can both do that in the physical world while they're learning in the simulator, think about that. This is what some of you and I have talked about, which is dual stream multimodal, meaning you can live in the virtual world with thousands of years worth of training, but you can also be taking in data right now and imitating what's happening right now. So both of them are happening at the same time. In fact, let's go a little bit deeper into what this actually means rather than outside the corporate commercialism of this. So what we have here is when you look at the schematic, the task prompt, you have the language, but you also have, I don't know if you can see this, videos and physical demonstrations, meaning mirror neurons in the real world. So you might have a demonstration from a real person, so they can get the tactile input. You have the videos of thousands of videos of this being seen in a non-physical environment, then you have language, which is the language learning models from OpenAI. This is where the LLMs come in, but then all of them are siphoned into Project GROOT and trained with a variety of different functions in the Omniverse. Okay, so what that ends up looking like is actions in the physical world. So once it goes into the virtual reality, the actions are made, they're put off into a human robot which then can reintegrate them and it's what's called a causal loop. This causal loop schematic is infinite learning. Okay, infinite recursive algorithms that use both physical world and virtual world simultaneously to create robots that can execute incredibly advanced systems and tasks. Okay, so you have basically massive martial arts training, you have militarized configurations, you have domestic configurations. Now of course they're going to be playing up everything from music to squeezing juice for you. Okay, so here's what it looks like in the domestic environment where it takes almost nothing. But once these, here's the thing to consider guys, just like a book, once you have the original copy, you can just take like an in printing press, you can just create more. Similar with robots, once you have the training program for anything, okay, then everybody knows. So everybody knows as much as all of them knows. That's not true in the human experience. So that gives you a little bit of an idea of what's going on and what I've been talking about in my other video, Get Ready for the Robots. This is actually moving very, very fast. Main takeaway I would like you to consider for your own life and what it means spiritually, emotionally, physically, intellectually, all these layers of what it means to be human is that the language learning models that everybody's talking about and oh, that's so cool, let's buy this new app and let's use LLMs to make my work faster. And then people are like, well, what are language learning models really for? There's got to be a limit of the data. No, there is no limit to the data because in that causal loop, there's an infinite amount of experience. Well, I'm not going to say infinite, but there is a unforeseeably large, predictably large data set. It's epigenetics in its function. It's taking what is in the astral plane or the metaphysical reality of the robots being trained while also the physical, or physical matter of phi cycle, the gravity-based function of the real universe and it's coupling those and integrating something better and using the logic between those couplings to become super human, super robotic. Okay, so that's really what's going on. This is important that the language learning models are just fodder. They're just fertilizer for the tech stack. So the big problem that has to be solved by NVIDIA is lowering the cost, better chips, more speed. This is what the nuclear power is about. If something seemed off to you about why would you need nuclear power to run a language learning model? Well, the big secret is that they're not sequestering nuclear facilities to create better data outputs and Microsoft Word writing documents and free article writers for the internet. They're sequestering this power and setting it aside so that they can build the stack to compress a million years into 30 seconds of training. In other words, a million years of training in the virtual world to be executed in 30 seconds by robot on the ground in the physical world. Think about what that means. It's beyond imagining. Imagine every physical possible experience and or executable task taught to a robot in 30 seconds or less. And of course that, that's the new compression. For gamers, it's been about speed on the screen and overclocking. Now it's all about the NVIDIA tech stack and how fast they can compress time inside the mind of a robot so that it can execute these unbelievably advanced systems and tasks in zero shot. Zero shot means there's no training in the physical world whatsoever. Okay, none. It's all acquired from its training internalized on its own astral plane or its own metaverse. Think about that, folks. All right, until the next video. Appreciate all of your comments and feedback. We're on team human. Let's address this thing together.